

Check whether AI sees your company
Get a free audit
Updated on 20 October 2026.
You have several hundred AI answers to review. You want to establish which ones recommend your company, which merely mention its name, and which contain inaccurate information about your offering. A brand mention counter alone will not explain this. You need a repeatable assessment method.
Jev from TypeSafe AI can act as an evaluation model in this process. It receives material and precisely defined questions, then returns results that software can compare, count and route for further work. In GEO, this is a potentially useful analytical layer for generative AI answers.
The main caveat: the model evaluates what you provide. Its output does not prove that a brand has a particular level of visibility across the internet. This guide describes possible applications and how to test them. It does not present a Jev test or a confirmed integration with Semly.
What is Jev, and how does it relate to GEO?
TypeSafe describes Jev as a System One model designed for fast, narrow evaluations. Instead of writing an article or a lengthy analysis, it returns a structured answer to a specific question. Its inputs are context, called “state” in the API, and a description of what should be evaluated. Source: introduction to Jev.
GEO, or Generative Engine Optimization, involves improving the presence of brands and content in generative AI answers. Jev can help organize the material used to make decisions. It is not a place where you gain a search engine position. Nor does it replace a system that collects answers from ChatGPT, Gemini or Perplexity.
A useful division of responsibilities is this: a separate process collects answers and sources, Jev evaluates specific features, software applies rules, and a person checks cases requiring interpretation. If a section of a page subsequently needs rewriting, that is a separate editorial task.
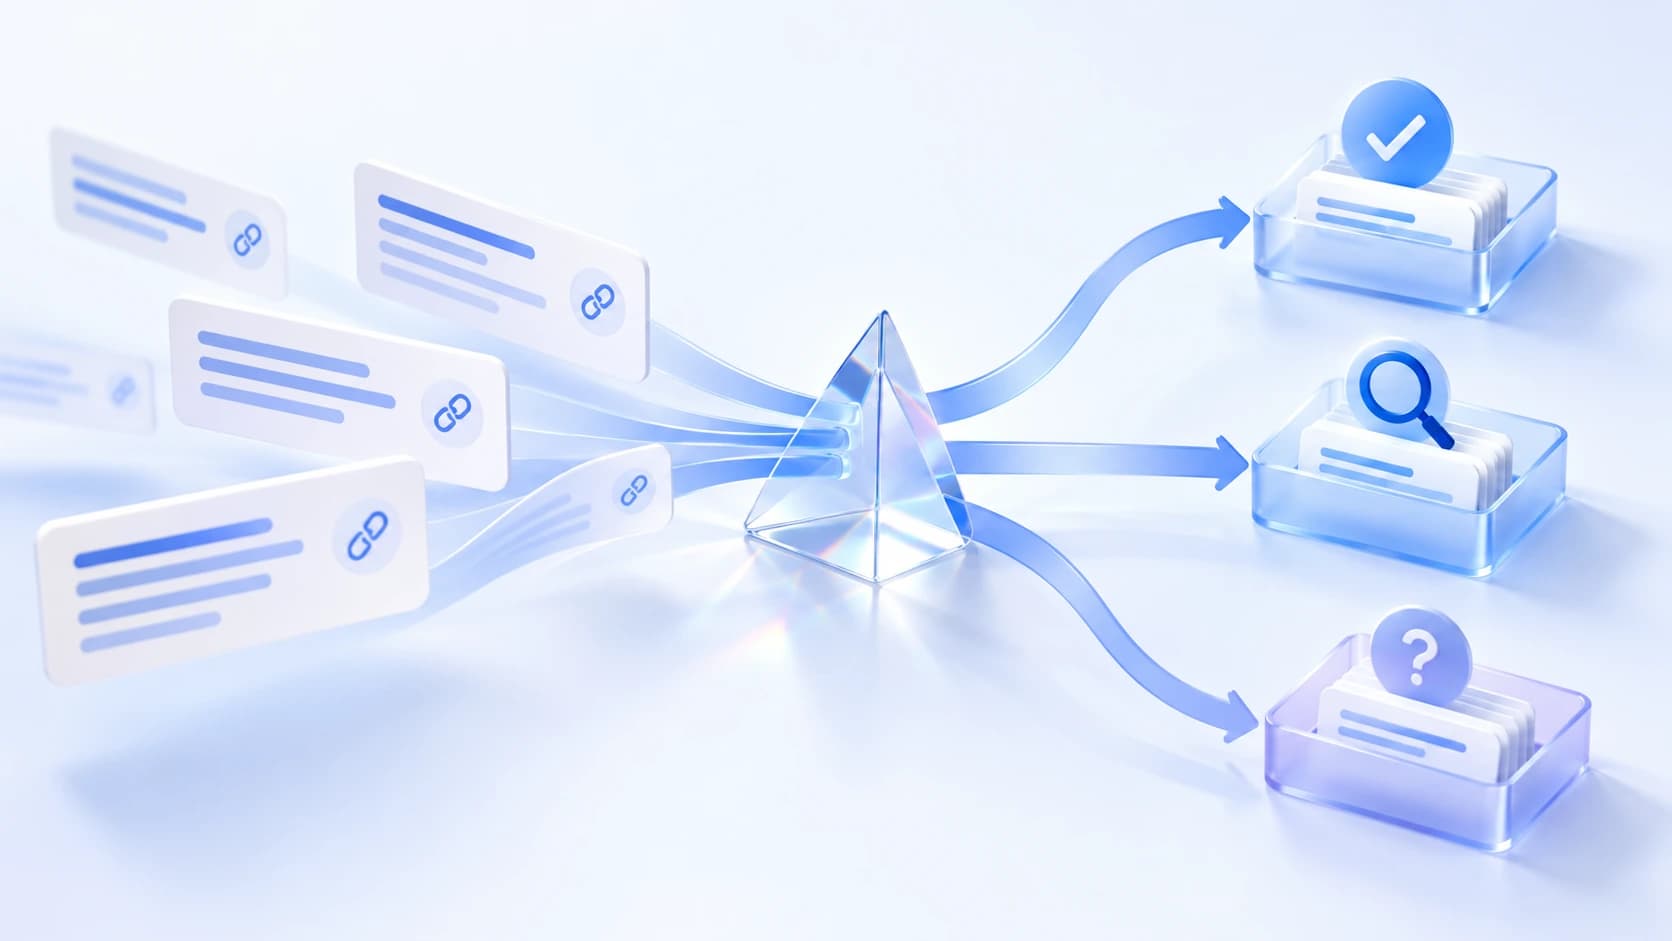
Illustrative diagram: recording answers, independent questions and checking results. Original editorial work based on TypeSafe documentation. The animation shows a proposed process, not a working integration.
Choice, Score and Noul: three ways to ask questions
Choose the question type to match the decision you actually need to make. “Is this answer good?” is too broad. You can break it down into whether a recommendation appears, whether facts are accurate, and whether the answer fully addresses the customer's need.
| Type | What question? | GEO example |
|---|---|---|
| Choice | Which defined category? | Neutral mention, recommendation or advice against a brand. |
| Score | Which level on a defined scale? | No answer, partial answer or all conditions covered. |
| Noul | Is the specified statement true? | Does the answer explicitly recommend the specified brand? |
Choice selects one category from a supplied set. Categories should be distinct, and criteria should cover borderline cases. If you are evaluating several features, such as recommendation and consistency with the offering, ask separate questions. Choice documentation.
Score requires ordered levels to be defined. “Does not answer,” “partially answers” and “answers all specified conditions” provide clearer criteria than a “quality 1-10” rating without a defined scale. The result reflects your definition of quality. Score documentation.
Noul returns the probability of a “yes” answer. A value close to 0.5 signals uncertainty, not partial satisfaction of a condition. The question must clearly state what “yes” means. Noul documentation.
What is current in October 2026?
According to the documentation checked on 20 October, the latest documented version is Jev 1.14, available since 14 October 2026. The documentation distinguishes version identifiers from the moving aliases “latest” and “preview.” When testing, record the actual model version, because a change behind an alias can change results. Jev models and versions.
In the 1.14 announcement, TypeSafe also describes experimental support for images, larger context and the “box” type. The vendor notes these features have limited production readiness. The text evaluation process described here therefore does not assume their use. TypeSafe announcement of 14 October.
A correctly formatted result does not guarantee a correct assessment. A model can return an allowed category and assign it to the wrong case.
7 applications of Jev in GEO and SEO
The scenarios below are proposed applications of the model, not a list of Semly features or deployment results. Each requires defined criteria and an accuracy check on material that matches your task.
1. Distinguishing mentions, recommendations and advice against a brand
“Brand X operates in this market” does not mean the same as “brand X is worth considering for this use case.” “Brand X does not support this use case” has a different meaning again. All three contain the company name, but only one is a recommendation in the described context.
You can ask Jev to assess an answer's stance toward a specific brand. Include the user's full question in the context, because recommendations can be conditional: a product might suit a small store but fail to meet a large organization's requirements.
Record name presence, positive recommendation and links separately. A link to the manufacturer's website can accompany either a recommendation or a critical assessment of the product.
The example data explains the method and does not represent any brand's results. The labels in the animation and subsequent examples were prepared editorially; they do not come from Jev calls. The same point is stated here in text: neutral mention, recommendation and advice against a brand are different assessments, regardless of whether a link appears.
2. Preliminary assessment of whether a source supports a claim
Detecting a URL itself is usually best handled through software rules. The question requiring judgment is whether a specific source passage supports a specific statement in an AI answer.
Split a sentence containing several promises into individual claims. Attach the relevant page passage, scope of the offering and retrieval date to each. If the source could not be retrieved, flag missing material. Do not turn that into a “source does not support the claim” assessment.
Depending on the questions designed, the model can provisionally flag agreement, contradiction or a need for review. We describe the full audit method separately: do cited sources confirm information about a company?.
3. Organizing customer questions
Questions about price, implementation, limitations and offer comparisons need different answers. Classification helps organize the analysis list and assign questions to the responsible people.
Decide whether one question can have multiple intents. “How much does implementation cost, and does it include migration?” concerns both price and scope. You can split it into two tasks or evaluate both dimensions separately. A forced single category can hide an important need.
Do not automatically infer demand size from the number of questions. Many similar formulations may come from the same source and concern a single need.
4. Checking whether a page answers the conditions in a question
A customer asks for a solution for a specific use case, with a particular integration and a budget limit. The page describes the product but does not explain compatibility. Using a defined completeness scale, the model can provisionally flag this gap.
Assess each condition separately. Missing information about an integration does not mean the product lacks it. It means the supplied content does not resolve the question. The next step is to verify the fact and supplement the description if that information will help the reader.
A high Score is neither a Google ranking score nor the probability of a ChatGPT citation. It is an assessment of specific material against your criteria.
5. Identifying page pairs for cannibalization review
First, select candidate pairs using subject matter, queries or content similarity. Then you can assess whether they answer the same need or support different decisions.
The model should receive the main question, target reader and content of both pages. Similar words in titles are insufficient. The output should create a list for editorial review. A decision to merge pages requires consideration of their value, traffic and role within the website.
We describe a practical topic split in our guide to a blog and knowledge base without cannibalization.
6. Assessing the usefulness of a proposed internal link
From candidate links, choose those that help readers take the next step. An article about choosing a solution can link to data preparation instructions if the reader needs them after making the decision.
The model's question should concern the usefulness of the connection within a specific paragraph. Topic similarity alone is insufficient. Software can separately check whether the URL works, while an editor checks whether the link text reads naturally.
7. Routing promises and comparisons for review
Before publication, passages containing prices, timelines, guaranteed outcomes or competitor comparisons can be flagged. This detection helps route the text to someone familiar with the current offering.
This is a review stage, not automatic confirmation of truth. The model cannot establish whether a company actually launches a service in one day without a reliable source for that information. If no source exists, the article needs editorial work.
How do you design a process that can be checked?
Start with one task, such as recognizing recommendations of a particular brand. Document the definition of a recommendation, excluded cases and handling rules for incomplete answers. Build automation only after that.
Keep the original material together with the question, AI product name, mode, language and date. An isolated sentence may receive a different assessment from the full answer. No answer, retrieval failure and an answer without the brand should have separate labels.
Several independent questions about the same material can be sent in one request. Combine their results using software rules. If a subsequent question requires data retrieved only after the first result, another stage is needed. TypeSafe question design principles.
Material -> separate questions -> rules -> result or human review.
Missing source -> supplement the material. Uncertain assessment -> verification. Changed definition -> repeat the test.
Store both the assessment and the criteria version in the report. When you change the definition of a recommendation, recalculate compared periods under the same rules or flag a break in comparability. Otherwise, an improved classifier can look like increased brand visibility.
Confidence is not a percentage guarantee of correctness
For Choice and Score, the documentation describes a “confidence” field calculated from the probability distribution. It indicates how decisive the model's result is. You should not automatically interpret 0.9 as confirmed 90% accuracy on your AI answers. Noul does not return a separate “confidence” field. How TypeSafe describes answer confidence.
Choose the review threshold based on testing the specific task. You may require a different confidence level for sorting a queue than for using an assessment in a client report. High confidence does not remove the need for quality control.
Do not discard uncertain cases from measurement without showing their number. If the model struggles more often with answers in one language, a report covering only easy cases can distort comparisons.
How to check accuracy: an example using 120 answers
In the example data, an editor assessed 120 answers. The model labeled 30 as recommendations. Comparison with the editor's assessment showed that 24 labels were correct and 6 were wrong. The model also missed 8 recommendations.
| Model assessment | Recommendation according to the editor | No recommendation according to the editor |
|---|---|---|
| Recommendation | 24 correct detections | 6 false alarms |
| No recommendation | 8 missed recommendations | 82 correct non-recommendation assessments |
| Total | 32 answers | 88 answers |
Recommendation precision here is 24 / 30 = 80%. That means one in five detected recommendations is a false alarm. Recall is 24 / 32 = 75%, because there are 32 actual recommendations according to the editor's assessment. The model missed a quarter of them.
Overall agreement is 106 / 120, or approximately 88.3%. This figure looks better because most answers contained no recommendation. On its own, it is insufficient to assess the classifier's usefulness.
In practice, prepare separate examples for refining the criteria and a separate set for final checking. Include negations, conditional recommendations, similar company names and incomplete sources. Have two people assess part of the material. Disagreements may expose an unclear definition before you begin evaluating the model.
The number 120 illustrates the calculations and is not a validation standard. Sample size and acceptable error levels depend on the purpose. Test Polish material in Polish: TypeSafe identifies English as the language in which it currently achieves the best accuracy. Language support documentation.
How much does Jev cost, and how much does the whole GEO process cost?
The model pricing checked on 20 October 2026 lists USD 0.042 per million input tokens. A token is a unit of text billed by the API. According to the documentation, output tokens are free. This is the vendor's rate on the verification date, not a guarantee of future prices. Pricing in the model documentation.
In the example data, you want to evaluate 2,000 answers, and each request averages 1,200 input tokens, including context and questions. The calculation is: 2,000 × 1,200 = 2,400,000 tokens; 2.4 × USD 0.042 = USD 0.1008, or approximately USD 0.10 for this part of the work.
This calculation uses an assumed input size; it is not a measurement of completed calls. A second full pass of the same size would double the cost to approximately USD 0.20. Longer context and retries also increase usage.
| Process element | Included in the stated USD 0.10? | What to account for? |
|---|---|---|
| Jev evaluation | Yes, under the example assumptions | Actual number of input tokens. |
| Collecting AI answers | No | An API, an answer collection service or manual work. |
| Retrieving and retaining sources | No | Page access, content extraction and storage. |
| Quality checking | No | Sample labeling, disagreements and human review. |
| Preparing content changes | No | Editing, fact-checking and implementation. |
Cheap classification therefore does not mean GEO monitoring for a few cents. Compare the cost of the entire run and the cost of obtaining a correct, useful result. A low price per assessment can become irrelevant if every result later needs manual correction.
What do the vendor's benchmarks not prove?
TypeSafe's public evaluation page describes four automation workflows. It evaluates models against reference labels determined by other models. This is a comparison within a particular test setup, not an independent assessment of Jev's accuracy in Polish GEO. TypeSafe evaluation methodology.
Do not apply a single number from such a chart to brand recommendations, cannibalization detection or citation accuracy. It also does not prove that using Jev will increase recommendations of a company. That conclusion would require a separate assessment of visibility changes and the conditions in which they were measured.
Will Jev help you earn citations in Google and ChatGPT?
It may help identify content gaps or organize answer evaluation. Simply running the model, however, does not cause an external search engine to read a page, judge it valuable and cite it in an answer.
Google states that SEO fundamentals apply to appearing as a source in AI Overviews and AI Mode. A page must be indexed and eligible to appear with a snippet. Meeting requirements does not guarantee inclusion. These guidelines concern Google's features, not a shared specification for all assistants. Google Search Central: AI features and your website.
Use evaluation to improve a page's answer for the reader: add conditions, explain limitations, provide a source or distinguish similar guides. Google recommends helpful content created for people. Its spam policies cover scaled content created primarily to manipulate results. Helpful content and spam policies.
Where should your company start?
First, establish the business question you need answered. Do you want to know whether AI recommends your brand? Whether it describes the offering accurately? Whether sources support specific claims? Each task requires different criteria.
If you are just starting, check your company's presence and read the answers in full. Once you know what you want to assess, prepare a manually labeled sample. Jev is worth testing when the task is repeatable and you can explain how you recognize a correct result.
Frequently asked questions about Jev and GEO
Will Jev write an article for GEO?
Jev is designed for structured evaluations, not free-form article writing. In the proposed process, it can assess a specific feature of a text. Content creation and editing remain separate tasks.
Will Jev independently check what ChatGPT says?
In the described process, you provide the answer and the necessary context. Collecting answers, retaining sources and documenting measurement conditions require separate handling.
Can a company rank in Jev?
Jev is not described in this article as a search engine that presents company rankings to customers. It can support analysis of material used in visibility work.
Does high confidence mean you can skip human review?
The decision depends on accuracy verified for your task and the consequences of an error. Model confidence is not independent confirmation of correctness. Keep a review path and regularly check automatically accepted results as well.
Does Semly use Jev?
This article does not confirm a Jev deployment within Semly. It presents possible applications of the model in GEO and SEO analysis, including limitations and a proposed test.
Documentation and sources were checked on 20 October 2026. Feature and pricing descriptions come from TypeSafe materials. Scenarios, diagrams and example data are editorial work and do not represent results from Semly brands or customers.
Share:
